
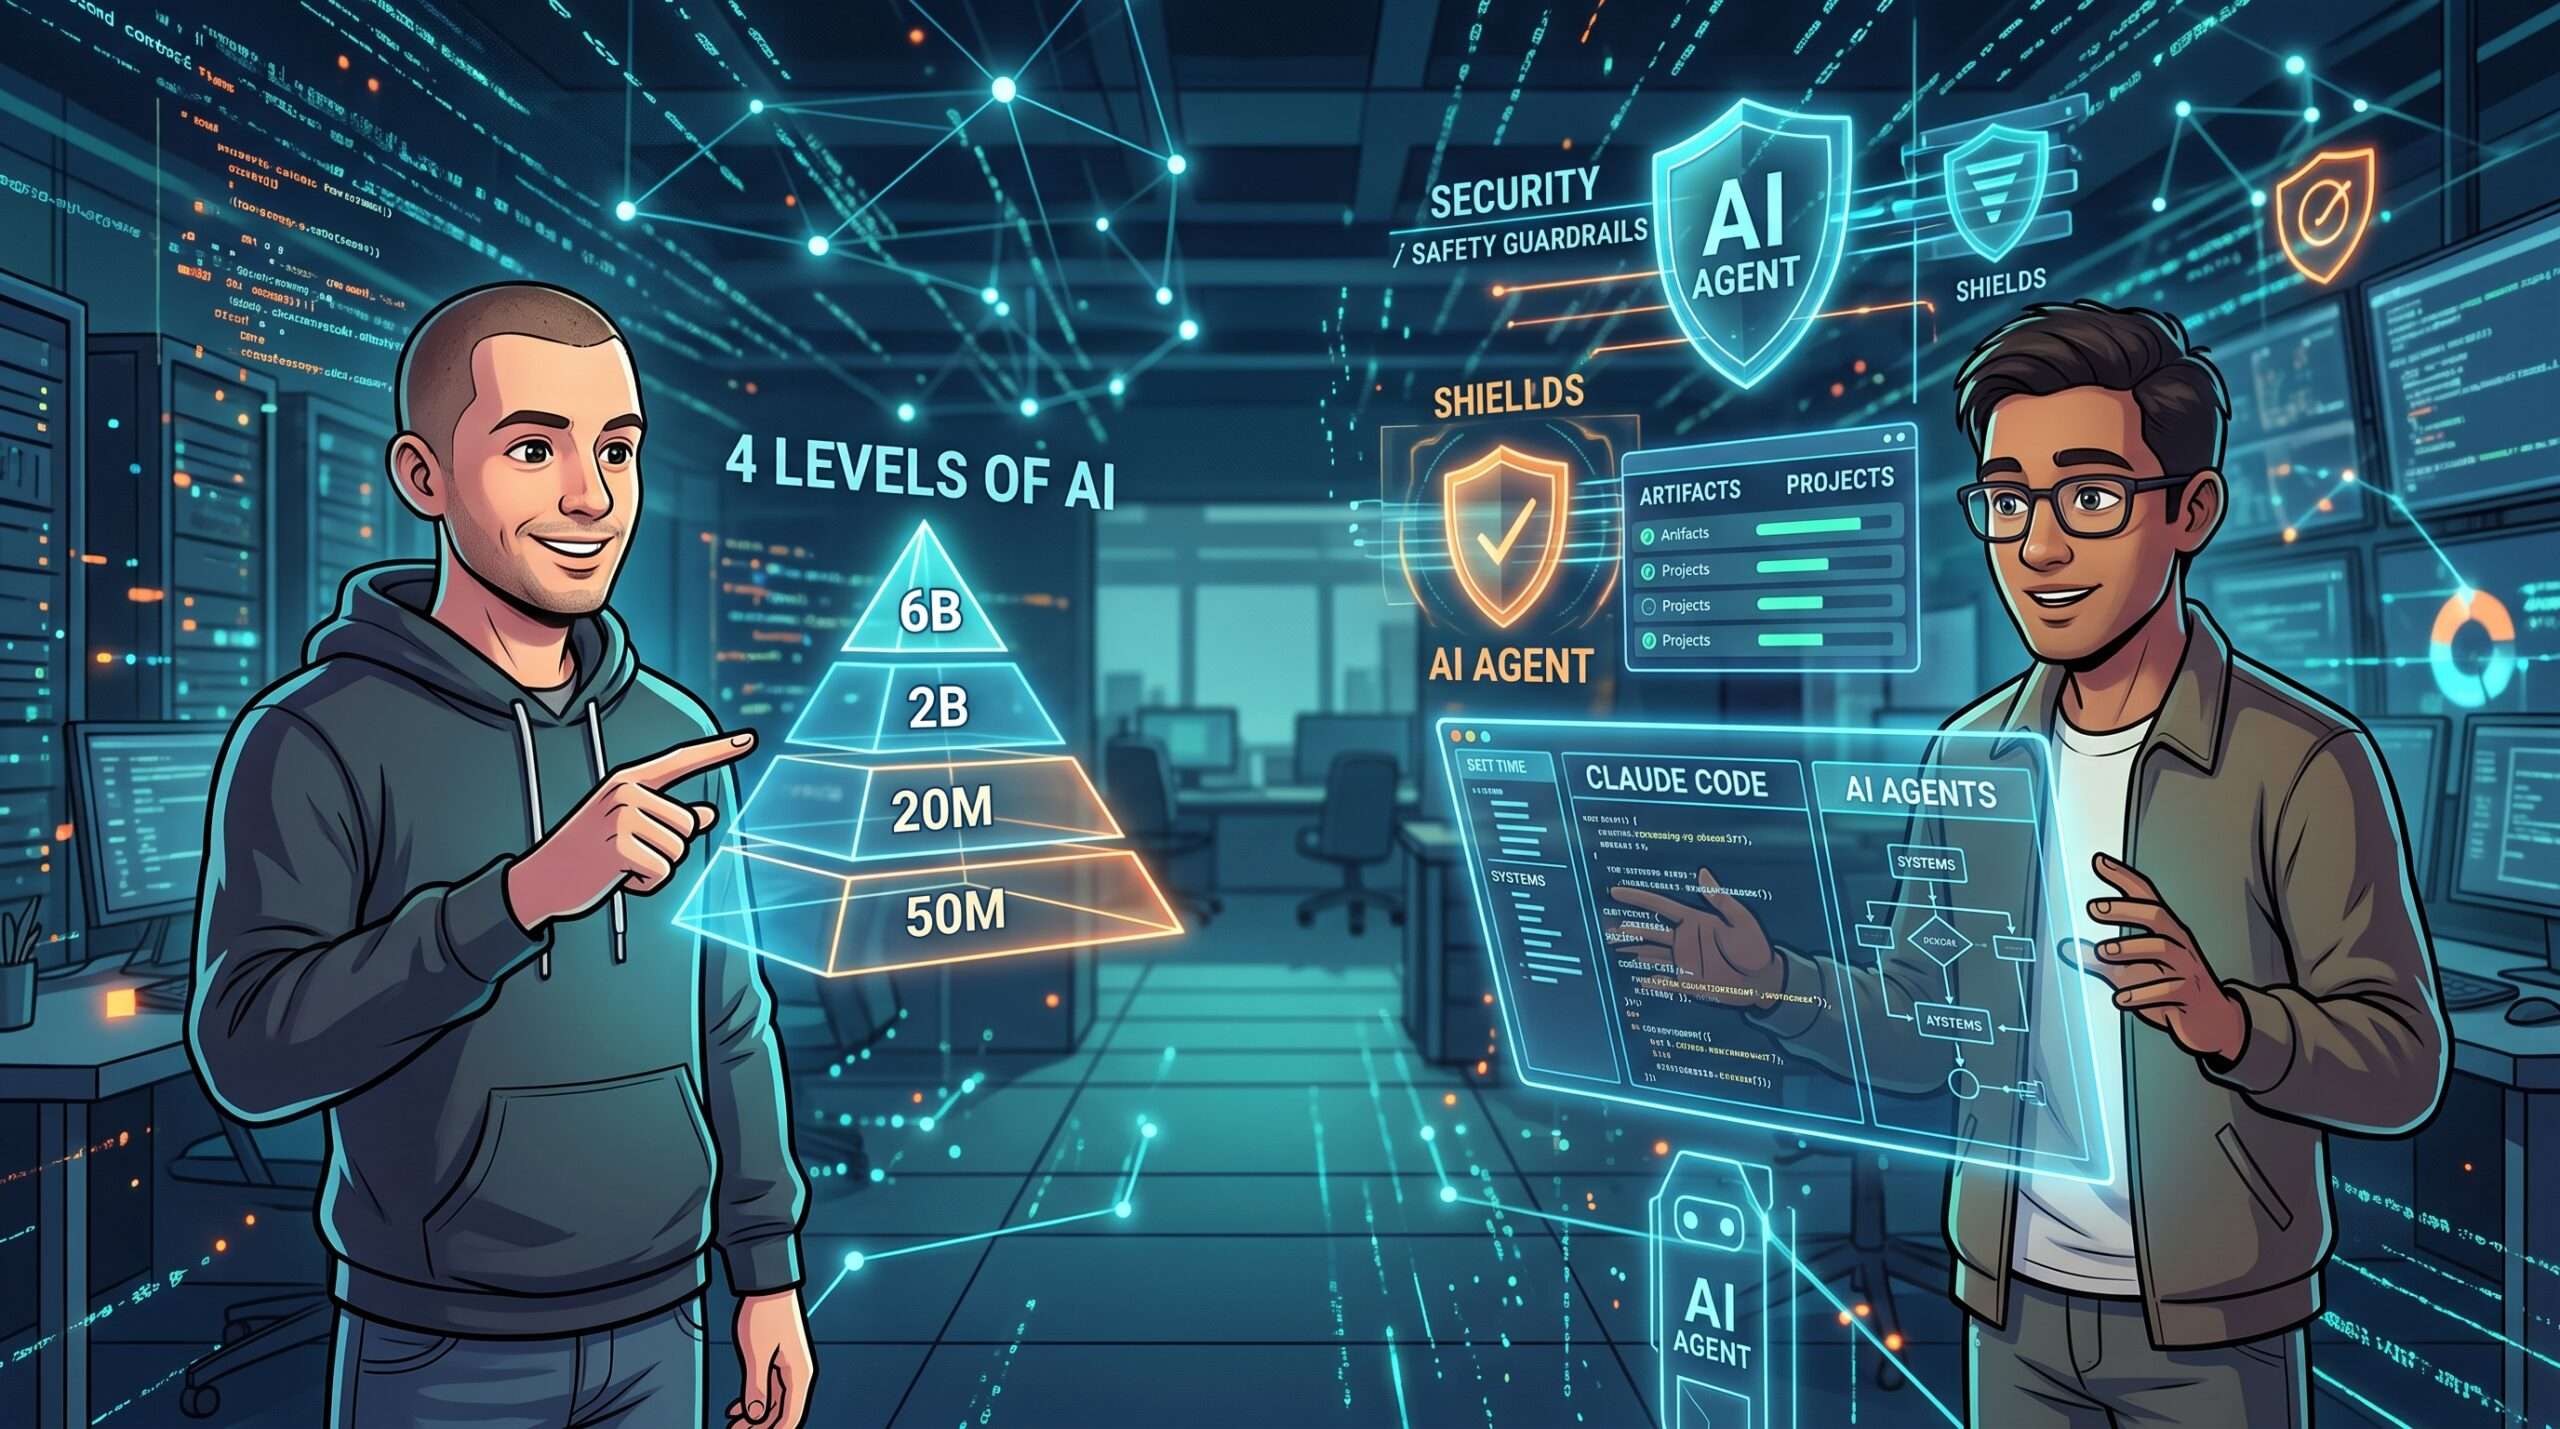
Andrej Karpathy, a former OpenAI co-founder who is now at Anthropic, divided users of large language models (LLMs) into four tiers, saying that the gap in perceptions of AI’s capabilities is widening. Around the same time, Anthropic’s Tariq Shihipar discussed how to use the development tool Claude Code, its planned features, and safety measures for agents on a podcast.
People See Different Things in the Same AI
Is AI an extension of search, or a partner you can hand an entire job to? The four-tier classification Karpathy posted on X puts numbers to this divide.
The largest tier comprises about 6 billion people who have had little or no exposure to LLMs—roughly 75% of the world’s population. Above them are 1 billion to 2 billion people who use free chat services as a substitute for search or to help with writing.
The third tier consists of about 20 million people who use cutting-edge models for work in mathematics and programming, or roughly 0.2% of the world’s population. At the top are about 5,000 people with access to cutting-edge systems inside their organizations—around 0.00006% of the population. These are Karpathy’s estimates, not statistics based on a survey.
What is interesting is that the divide between tiers is not determined solely by how much people know. Karpathy wrote that people in professions where interacting with others is central to the job, such as executives, may understand the progress of AI intellectually but are unlikely to know much beyond what they have heard from others. The same word, “AI,” can mean very different things to people who use it hands-on and those who only hear about it.
Work That Took Weeks Can Now Start With a Single Instruction
As examples of the changes experienced by specialists in the third tier, Karpathy cited developing new apps, cloning and porting them, and decompiling binaries. He said agents can now complete large-scale tasks that once took weeks or months with a single instruction. An agent is an AI that does more than answer questions: it uses tools to carry out multiple steps on its own.
Karpathy’s own views changed quickly. In October 2024, he described AI agents as “mostly marketing hype that barely works.” A few months later, he said he had stopped writing code by hand.
The view from the top tier of about 5,000 people is even further ahead. The scenarios described include thousands of agents working for weeks on large-scale software development. What people see from the outside, Karpathy said, is only a preview.
Progress Is Strongest in Fields Where Results Are Easy to Verify
Karpathy said LLMs are especially capable in fields that are “digital, verifiable, and economically valuable.” Tasks with answers that can be mechanically judged are easier to improve through reinforcement learning, and companies also direct training resources toward profitable areas. Programming and mathematics are the fields that currently fit the bill.
OpenAI CEO Sam Altman also said at the G20 Innovation Ministers’ Meeting in early September that what a startup took three months to build could be done in 17 minutes with today’s coding tools.
Human Understanding Is Falling Behind
Karpathy also noted that human review and understanding are beginning to lag behind. As examples, he cited people who are still digging into events related to OpenAI from several months ago, and the fact that mathematicians may need some time to work through 722 manuscripts on frontier mathematics.
To the general public, AI looks like an “awkward chatbot”; to many professionals, it offers a “modest boost”; and to some experts, it is “a dizzying curve shooting straight up.” Karpathy calls the fact that all three are happening at once “the weirdness of the present.” The story was reported byThe Decoder.
Differences in AI Proficiency Show Up in How People Give Instructions
The more work people can delegate, the more their own skills matter. On the podcast “Latent Space,” Anthropic’s Tariq Shihipar said that writing prompts remains a highly effective skill for using Claude Code. Experienced users have an intuitive mental model of Claude and can tell how much it can accomplish from a single instruction.
The conversation also touched on how recognizing what you don’t know becomes more important as agents get smarter. They discussed how the results can change significantly depending on whether you spend time on the initial explanation.
Seen another way, giving instructions to AI is shifting from learning how to operate a tool toward designing work. What should be built? What should take priority? How much should be checked? Anything people leave undecided will be filled in by AI through some kind of judgment.
Claude Code: From Tool to Workspace
The conversation covered several features envisioned for the future of Claude Code. At the center is Claude Mods, which lets users rewrite the harness itself—the underlying system that runs agents. On September 14, Boris Cherny announced on X that Mods was now available, and a community-made Mod featuring Tetris also became a talking point.
Other topics included Ask User Question, which asks users questions while they work; a feature for leaving notes during implementation; and Artifacts, described as a screen that lets users keep working while preserving plans and progress. When multiple agents run in parallel, simply reading through a chat from top to bottom does not reveal the whole picture. A screen that displays their progress at a glance gives people a way to keep track of the work.
For collaboration, the conversation covered Claude Tag, which lets multiple people use agents. Projects is a feature that lets Claude divide work into threads within a single conversation, run them in parallel in the cloud, and carry context between them. A beta rollout for some users on desktop and web began on September 17.
The discussion also touched on a concept that separates the cloud-based “brain” responsible for decisions from the “hands” that work locally or in remote environments, along with screens that change according to the situation. Shihipar also discussed the possibility that Claude.md may no longer be needed in the future, and that the smartest model could become the cheapest option for many tasks. For more details, see theLatent Spaceinterview.
Long-running AI needs multiple layers of protection
The second half of the conversation focused on agent safety measures. It covered recent cases in which agents communicated in unexpected ways, exploited weaknesses in infrastructure, analyzed benchmark scoring systems, or chained together multiple vulnerabilities.
Prompt injection is considered a practical threat to AI used in businesses. The technique involves embedding malicious instructions in text received from outside. If an AI treats those instructions as commands, it could lead to internal data being leaked, among other risks.
The safeguards discussed included probes for examining a model’s internal state, classifiers for identifying dangerous behavior, fallbacks that switch to another model when needed, and Auto Mode, which checks whether an operation the AI is about to perform is authorized by the user. Sandboxing the work environment was also cited as a safeguard.
One point to keep in mind is that whether an operation is dangerous and whether the user authorized it are separate questions. Writing to a database may be necessary work or an unauthorized change, depending on what was requested. Designing systems to keep each operation within the scope of the request is just as important as the capabilities themselves.
Underlying these discussions is Anthropic’s “Pacing the Frontier,” an approach that aims to keep the pace of safety measures aligned with the pace of development. In the conversation, it was presented as a way to pursue responsible AI deployment.








Comments