
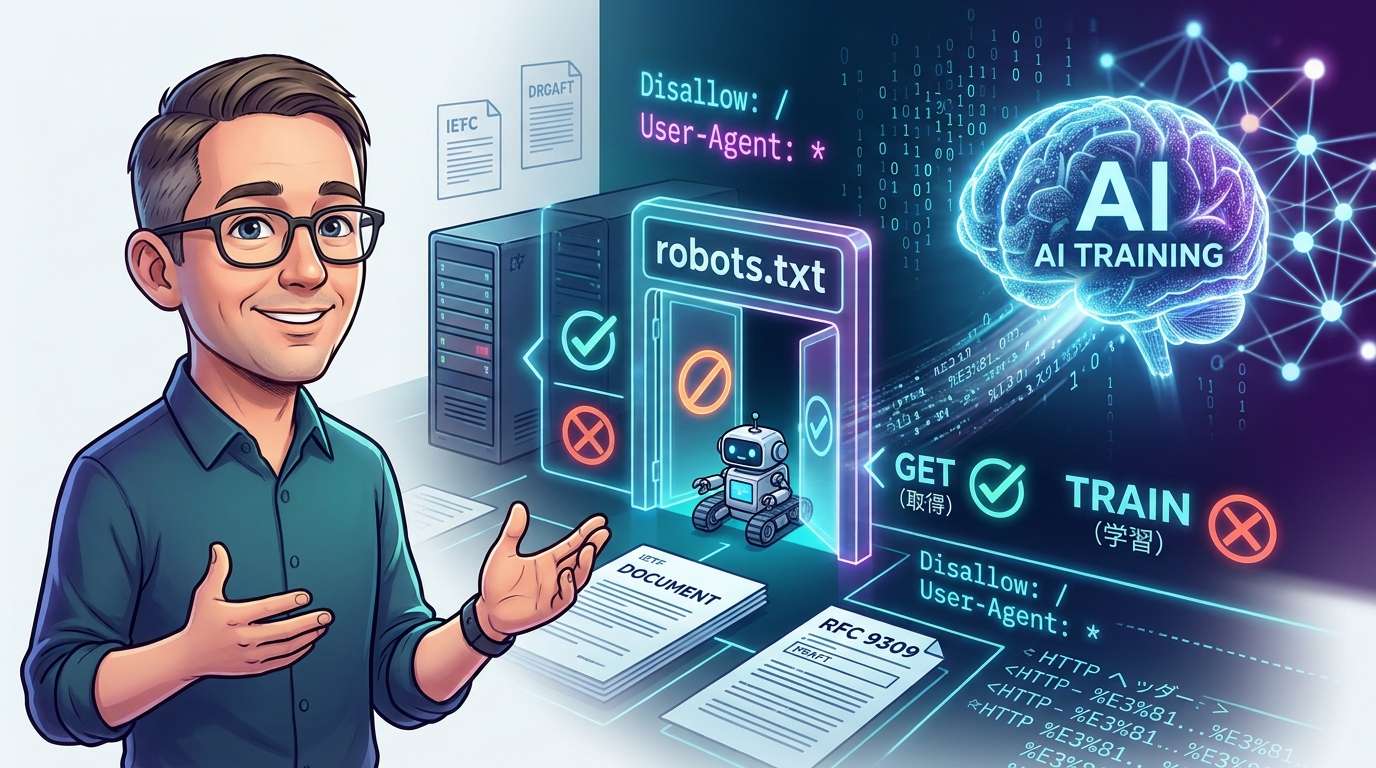
In the second episode of Search Central’s video series “The Non-Canonical Cabinet,” Google’s Gary Illyes explained that under the standard RFC 9309, robots.txt specifies which URLs crawlers may fetch, but does not determine how data is handled after it has been fetched. He said that anyone who wants to block a particular AI crawler needs to name that crawler’s user agent explicitly.
“Disallowing access” and “preventing training” are two different things
The idea that “you’re safe if you put a ban on AI training in robots.txt” seems to be gradually gaining traction. But Illyes’s explanation shows that it is not that simple. robots.txt is like a sign at a website’s front door saying, “You may enter through this door.” What visitors do with the information they take away is beyond the sign’s scope.
Illyes described robots.txt, as defined by RFC 9309, as “a protocol for communicating access preferences,” and said it cannot instruct systems on how to handle data they have already crawled. The question raised in the video was whether it is possible to allow AI crawling while preventing the same information from being used to train generative AI models. The answer is that robots.txt alone cannot make that distinction.
robots.txt only controls access
Google’s documentation lists four directives it supports: User-Agent, Allow, Disallow and Sitemap. Any other lines are invalid and ignored. The video showed a fictional directive called “No-AI-Chicken-Training,” but Google’s parser does not read custom lines like this.
Section 2.2.4 of RFC 9309 leaves it up to each crawler to decide how to handle records outside the scope of the specification. In other words, even if you add a custom line, whether the other party honors it is up to them. It might work, or it might not. At the very least, it is not a “commitment protected by the standard.”
The reliable practical approach is to specify the user agent of each AI crawler you want to stop and use Disallow to deny it access. Illyes said that if you want to block access to the entire site, you need to explicitly list the relevant token.
Google-Extended is a Google-specific usage control
So how should Google-Extended, which is used for Google’s AI, be understood? It is a robots.txt token that does not have a separate user agent; Google crawls using its existing crawlers. The company’s crawler documentation says the token is used for “control.”
It controls whether content fetched by Google can be used to train future Gemini models, or for grounding in Gemini Apps and Grounding with Google Search on Vertex AI—that is, referencing information to support answers. It does not affect inclusion in Google Search and is not a search-ranking signal.
The key point is that this meaning of “usage control” comes from Google’s own product documentation, not RFC 9309. It does not apply to other companies’ AI systems as a common robots.txt rule. It is best understood as a dedicated switch for Google.
A standard proposal for specifying intended uses is still a draft
Could a site specify crawl permissions separately from its preferences for how fetched content is used? Work is underway to address this issue. Illyes is co-authoring an IETF Internet-Draft with Mozilla’s Martin Thomson. The current version, dated August 19, updates RFC 9309 by adding a “Content-Usage” directive to robots.txt and a corresponding HTTP header.
The division of responsibilities is straightforward. Allow and Disallow continue to determine which URLs can be crawled, while Content-Usage indicates how the site would like fetched content to be used. These preferences apply only to paths the crawler is permitted to fetch. In the draft’s example, a robots.txt file that allows crawling includes a Content-Usage entry reading “train-ai=n.”
However, the proposal is still a working-group document. According to the IETF Datatracker, it has not yet been submitted to the IESG (the Internet Engineering Steering Group, which oversees Internet standards) for review, and the working group is scheduled to submit it in August 2026. The “train-ai” label appears in a separate vocabulary draft dated September 14, but that document explicitly says it does not reflect working-group consensus. The current draft expires on February 20, 2027, and will be superseded if a revised version is published before then.
In short, a standard way to express preferences about training separately from crawler access remains only a draft for now. It is too soon to treat it as an established common rule that can already be used.
Percent-encoding is the safer option for Japanese URLs
This episode also covered practical topics beyond AI. Google’s Cherry Prommawin advised that when writing paths containing non-English characters or emoji in robots.txt, you should “use an encoded form.” Google’s parser can encode and process raw characters, but other crawlers, especially older ones, may get confused.
In the video, an example with emoji written as-is was labeled “works in Google, but may break elsewhere,” while a percent-encoded example was labeled “the safe, standard approach.” According to Google’s documentation, its parser treats raw UTF-8 and percent-encoding as equivalent. RFC 9309’s grammar also allows UTF-8 characters in paths, but crawlers from other companies may not interpret them the same way.
Many sites use Japanese directory or page names in their URLs. If you’re trying to control AI crawlers individually, it’s worth paying attention to how you write those paths.
What site operators can do now
To sum up, the steps to take depend on the bot or product in question if you want to limit AI use while preserving how your site appears in Google Search. You can block specific AI crawlers from accessing pages with a Disallow directive for their user agent. For Gemini, Google’s officially documented control is Google-Extended, which covers both training and grounding.
There is still no standard way to allow crawling while opting out of training; the only proposal so far is in a draft. We are not yet at a point where one line in robots.txt can decide everything, so for now it remains essential to check each crawler’s official documentation. As standardization advances, there may eventually be a way to specify access rules separately from preferences for how content is used.
The video description notes that the next installment in the series will cover the 404 status code.






Comments