
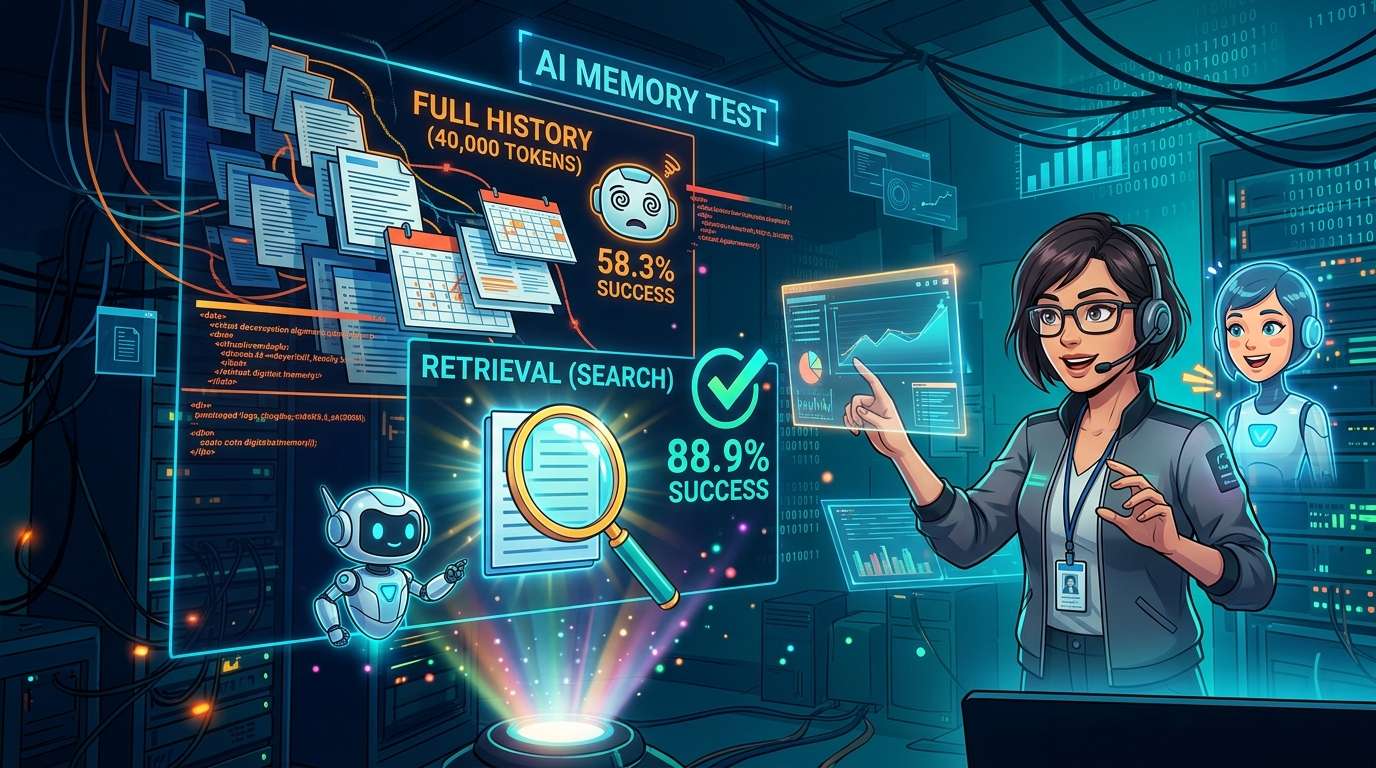
A test comparing four ways to give AI assistants “memory” has been published by data science outlet Towards Data Science. In an experiment using a fictional project manager’s history of about 40,000 tokens and 30 requests, GPT-4o mini had a task success rate of 58.3% when given the entire history, compared with 88.9% when using a retrieval approach that searches for and supplies only the relevant parts.
“Remembering” and “being able to use it” are two different things
The evaluation starts with a new test of AI memory called DolphinBench. The full text is available inthis evaluation article.
Many conventional memory tests directly ask about past facts, such as “Where is Sam’s favorite coffee shop?” But the creators of DolphinBench say the question itself gives away that the answer is recorded somewhere. So the test instead assigns a task—“Order coffee”—and checks whether the AI uses the correct fact.
The design gives three fictional people conversation histories of about 500,000 tokens each, then assigns 200 requests per person. Results must report not only accuracy but also cost and time.
The test was created by a company that sells a memory system called Mem0. In its announcement, the company said its configuration led the field, successfully handling 70.67% of requests. The author of this evaluation did not reproduce DolphinBench or test any specific company’s product. Instead, they borrowed the concept and built a small experiment of their own.
Four memory approaches tested with Dana, a fictional project manager
The experiment centers on Dana Whitfield, a fictional project manager. The author created a year’s worth of conversation history—80 conversations—and planted some details in it.
A year of history and 30 requests
The history totals about 40,000 tokens. Thirty of the conversations each state one fact, such as a regular lunch spot, meeting time, project launch date, or person in charge. Eleven later change one of those facts, while the remaining 39 are casual exchanges about things like printers, trains, and the weather. Everyday chatter is deliberately mixed in so the facts do not stand out.
There are 30 requests. Each involves calling a tool to schedule a meeting, order a meal, send a message, or assign a task; nine require two facts, such as a person in charge and a date. Scoring ignores the wording of the reply and checks only whether the values passed to the tool are correct. The experiment also includes one straightforward question about each fact to see whether the model can answer with the latest value.
The four approaches compared
There are four approaches: “No memory,” which supplies nothing; “Full history,” which provides all 40,000 tokens every time; “Summary,” which reads the history in stages and keeps rewriting a summary of about 1,000 words; and “Retrieval,” which selects and provides five history snippets relevant to the request.
In practical terms, the difference is whether you hand over a year’s worth of diary entries every morning, provide a one-page cheat sheet someone has put together, or pull out only the relevant pages each time a request comes in.
The models were OpenAI’s GPT-4o mini and Anthropic’s Claude Haiku 4.5, with 1,260 runs in total. Records of all the experiments are available on the experiment-tracking platform Weights & Biases.
Comments