
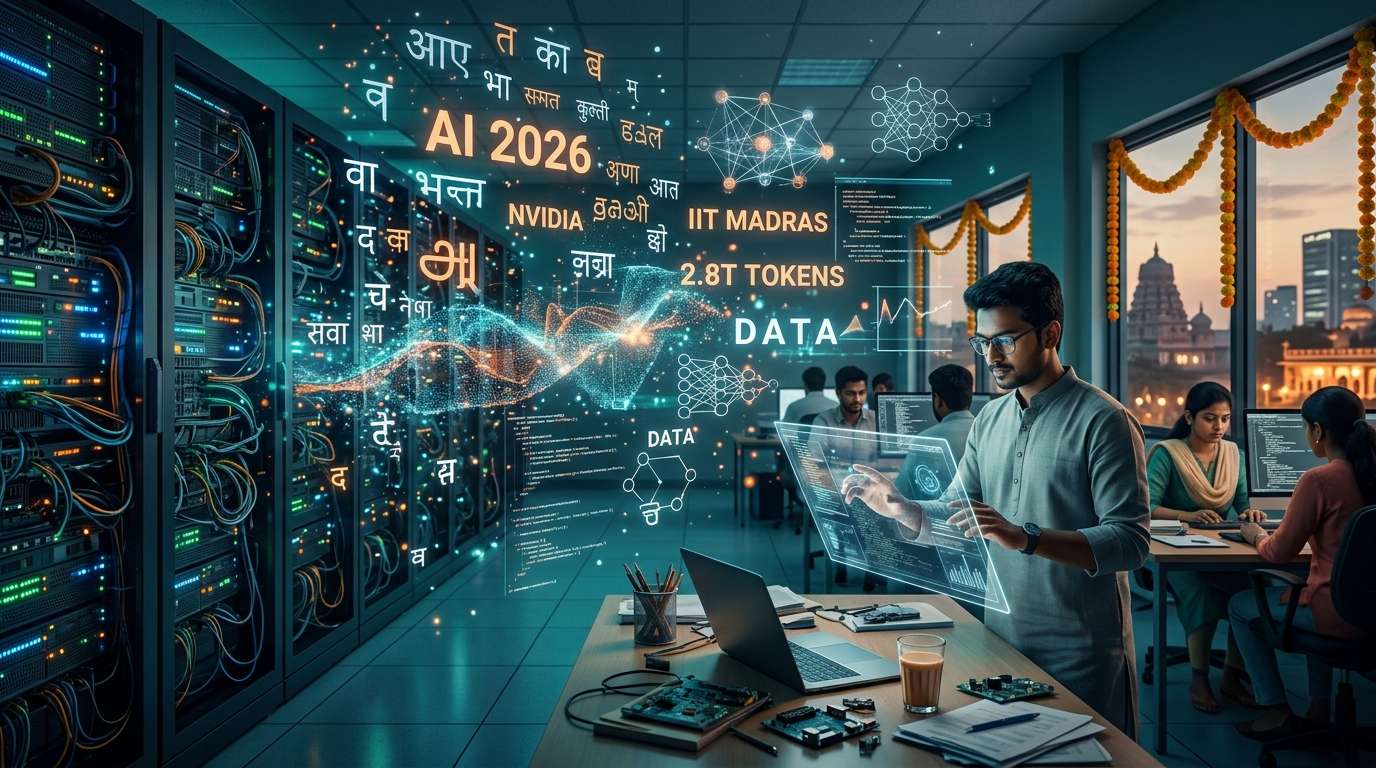
NVIDIA announced that it will soon release “Nemotron-pretraining-Indic-v1,” a dataset of about 2.8 trillion tokens for AI pretraining across the 22 languages listed in India’s Constitution, developed in collaboration with the Indian Institute of Technology Madras (IIT Madras) and its AI4Bharat initiative. The company also plans to release the GPU-compatible pipeline used to generate the data. The approach combines synthetic data based on English-language materials with natural text written locally.
A massive corpus covering 22 Indian languages in 34 configurations
The dataset covers the 22 languages listed in India’s Constitution. They include Hindi, Bengali, Tamil, Telugu, and Urdu, and are the first languages of about 97% of India’s population. Based on the 2011 census, that represents roughly 1.2 billion people.
AI training data for Indian languages is scarce compared with English. Mitesh Khapra, who leads AI4Bharat, has long highlighted this problem, and the new dataset is intended to help address the shortfall.
Let’s take a closer look at the contents. All 22 languages have data written in their standard scripts. For 12 of them, the dataset also includes versions transcribed into Latin characters, or the Roman alphabet, bringing the total to 34 language-and-script combinations. The standard-script data accounts for about 2.601 trillion tokens, and the Latin-script versions for about 224.6 billion. Both counts were measured using the Gemma-4 tokenizer.
One important caveat: these figures do not represent the number of “unique English documents.” Translations and versions in different scripts derived from the same sources are counted separately. The Latin-script versions are not translations into English; they are Indian languages written in a Romanized form. They can also serve as material for training on the same content in different scripts.
Given how many people type Hindi in the Roman alphabet in emails and on social media, this design is practical. For Japanese, it might be like training on both hiragana-and-kanji text and text entered using romaji.
A four-stage generation process that goes beyond translation
The source material consists of 15 subsets of Nemotron-CC-v2, including web text, question-and-answer content, mathematics, and code. NVIDIA’s open-source synthetic data generation tool, “NeMo Data Designer,” processes the material in an end-to-end workflow that covers translation, quality evaluation, and revision.
The outputs retain identifiers for the source documents, making it possible to trace which documents the data came from. This ease of later auditing is one of the strengths of open data.
For the 12 languages, the process has four stages: translating English documents, evaluating quality, revising low-scoring outputs, and converting them to the Latin script. Translation is handled by Gemma-4-31B-it, which translates entire documents at once to preserve context across paragraphs, tables, and equations. It is also worth noting that prompts instruct the model to leave code, equations, and URLs untranslated.
The same model evaluates the translations against the source text, assessing meaning, fluency, terminology, style, and formatting, with reference to MQM, a framework for classifying translation errors. Outputs scoring 75 or higher out of 100 are accepted. Those below the threshold are revised using evaluation feedback and scored again. This revision process salvaged 438.4 billion tokens across the standard- and Latin-script versions, and those tokens are already included in the total.
The Latin-script versions are also produced using a considered approach. Rather than romanizing directly from English, the process converts the accepted standard-script translation and then checks the result against the original translation. Early manual comparisons found that this two-step method introduced fewer fabrications and left less English in the text.
Dedicated translation models handle the remaining 10 languages
The 10 languages without Latin-script versions are Assamese, Bodo, Dogri, Kashmiri, Konkani, Maithili, Manipuri, Sanskrit, Santali, and Sindhi. Translation uses “Indic Translate,” a model developed by Bodhan AI, a nonprofit organization launched at IIT Madras.
Gemma-4-31B-it handles evaluation, using the same acceptance threshold of 75. However, outputs are not rewritten based on feedback, and only standard-script data is produced.
The process also includes language-specific adjustments. Long Santali documents are translated in overlapping windows and then reassembled. Manipuri is first translated into Bengali script and then converted into its own script, Meitei Mayek. These are examples of adaptations made necessary by the widely varying script situations across India’s languages.
What can we infer about performance gains?
One indication of the dataset’s impact comes from continued pretraining of Nemotron 3.5 Super VL. At this stage, 10% of the 100-billion-token training budget—10 billion tokens—was allocated to a mix of some of the 12 languages in the new corpus and naturally written Indian-language text. The remaining 90% retained the proportions of the earlier training mixture.
As a result, scores improved across all five benchmarks—MILU, Indic MMLU-Pro, Indic ARC-Challenge, Indic ARC-Easy, and Indic GSM8K—by 4.98 to 9.82 points. However, the comparison looks at checkpoints before and after continued pretraining; it does not isolate the contribution of synthetic data alone. What is clear is that the blend of synthetic data and natural text worked.
Looking at the completed model overall, scores rose on five of six task evaluations—covering knowledge, reasoning, math, code, and translation—compared with the previous-generation Nemotron 3 Super. IFEval 1.5, which measures instruction following, fell by 2.04 points.
On Sarvam AI’s “IndiVibe” evaluation, which measures dialogue quality in Indian languages, all four categories improved: helpfulness, fluency, fidelity to language and script, and appropriateness of answer length.
More Than a Data Release: Making the Most of It
What stands out about this release is that it opens up not just the data itself, but also “how it is made.” The “Nemotron Bharat” translation plugin for NeMo Data Designer includes prompts for translation and evaluation, rewriting functionality, document windowing, and script-conversion support. Companies and research institutions with their own documents can use the same process to create data for other domains.
The guidance on how to use it is also specific: start by testing a small sample of your own documents, checking whether code, equations, and formatting are preserved, and scale up only after review by speakers of local languages. The plugin returns candidates and scores, so each team’s selection policy determines which records are included in training. The data can be loaded using Hugging Face’s streaming feature, allowing users to inspect its contents without downloading the full dataset.
Translated data cannot replace text written locally. Naturally written text carries regional knowledge and cultural context. This corpus is designed to be used in combination with that kind of text.
Quality evaluation is largely automated, with human review focused mainly on samples. In the 12-language workflow, the model used for translation also serves as the evaluator, so the 10-language workflow calls for broader validation by native speakers. Deduplication by source ID removes duplicates introduced during processing; it does not identify and group similar content based on meaning.
With NVIDIA’s support, AI4Bharat is also building the “Indic-LLM-Eval-Suite,” a collection of evaluation benchmarks. Efforts to expand the data are progressing alongside efforts to establish standards for measuring it. Can an AI foundation that has been centered on English be strengthened through language-specific evaluation and a blend with natural text? This corpus for India’s 22 languages could be a litmus test.








Comments