
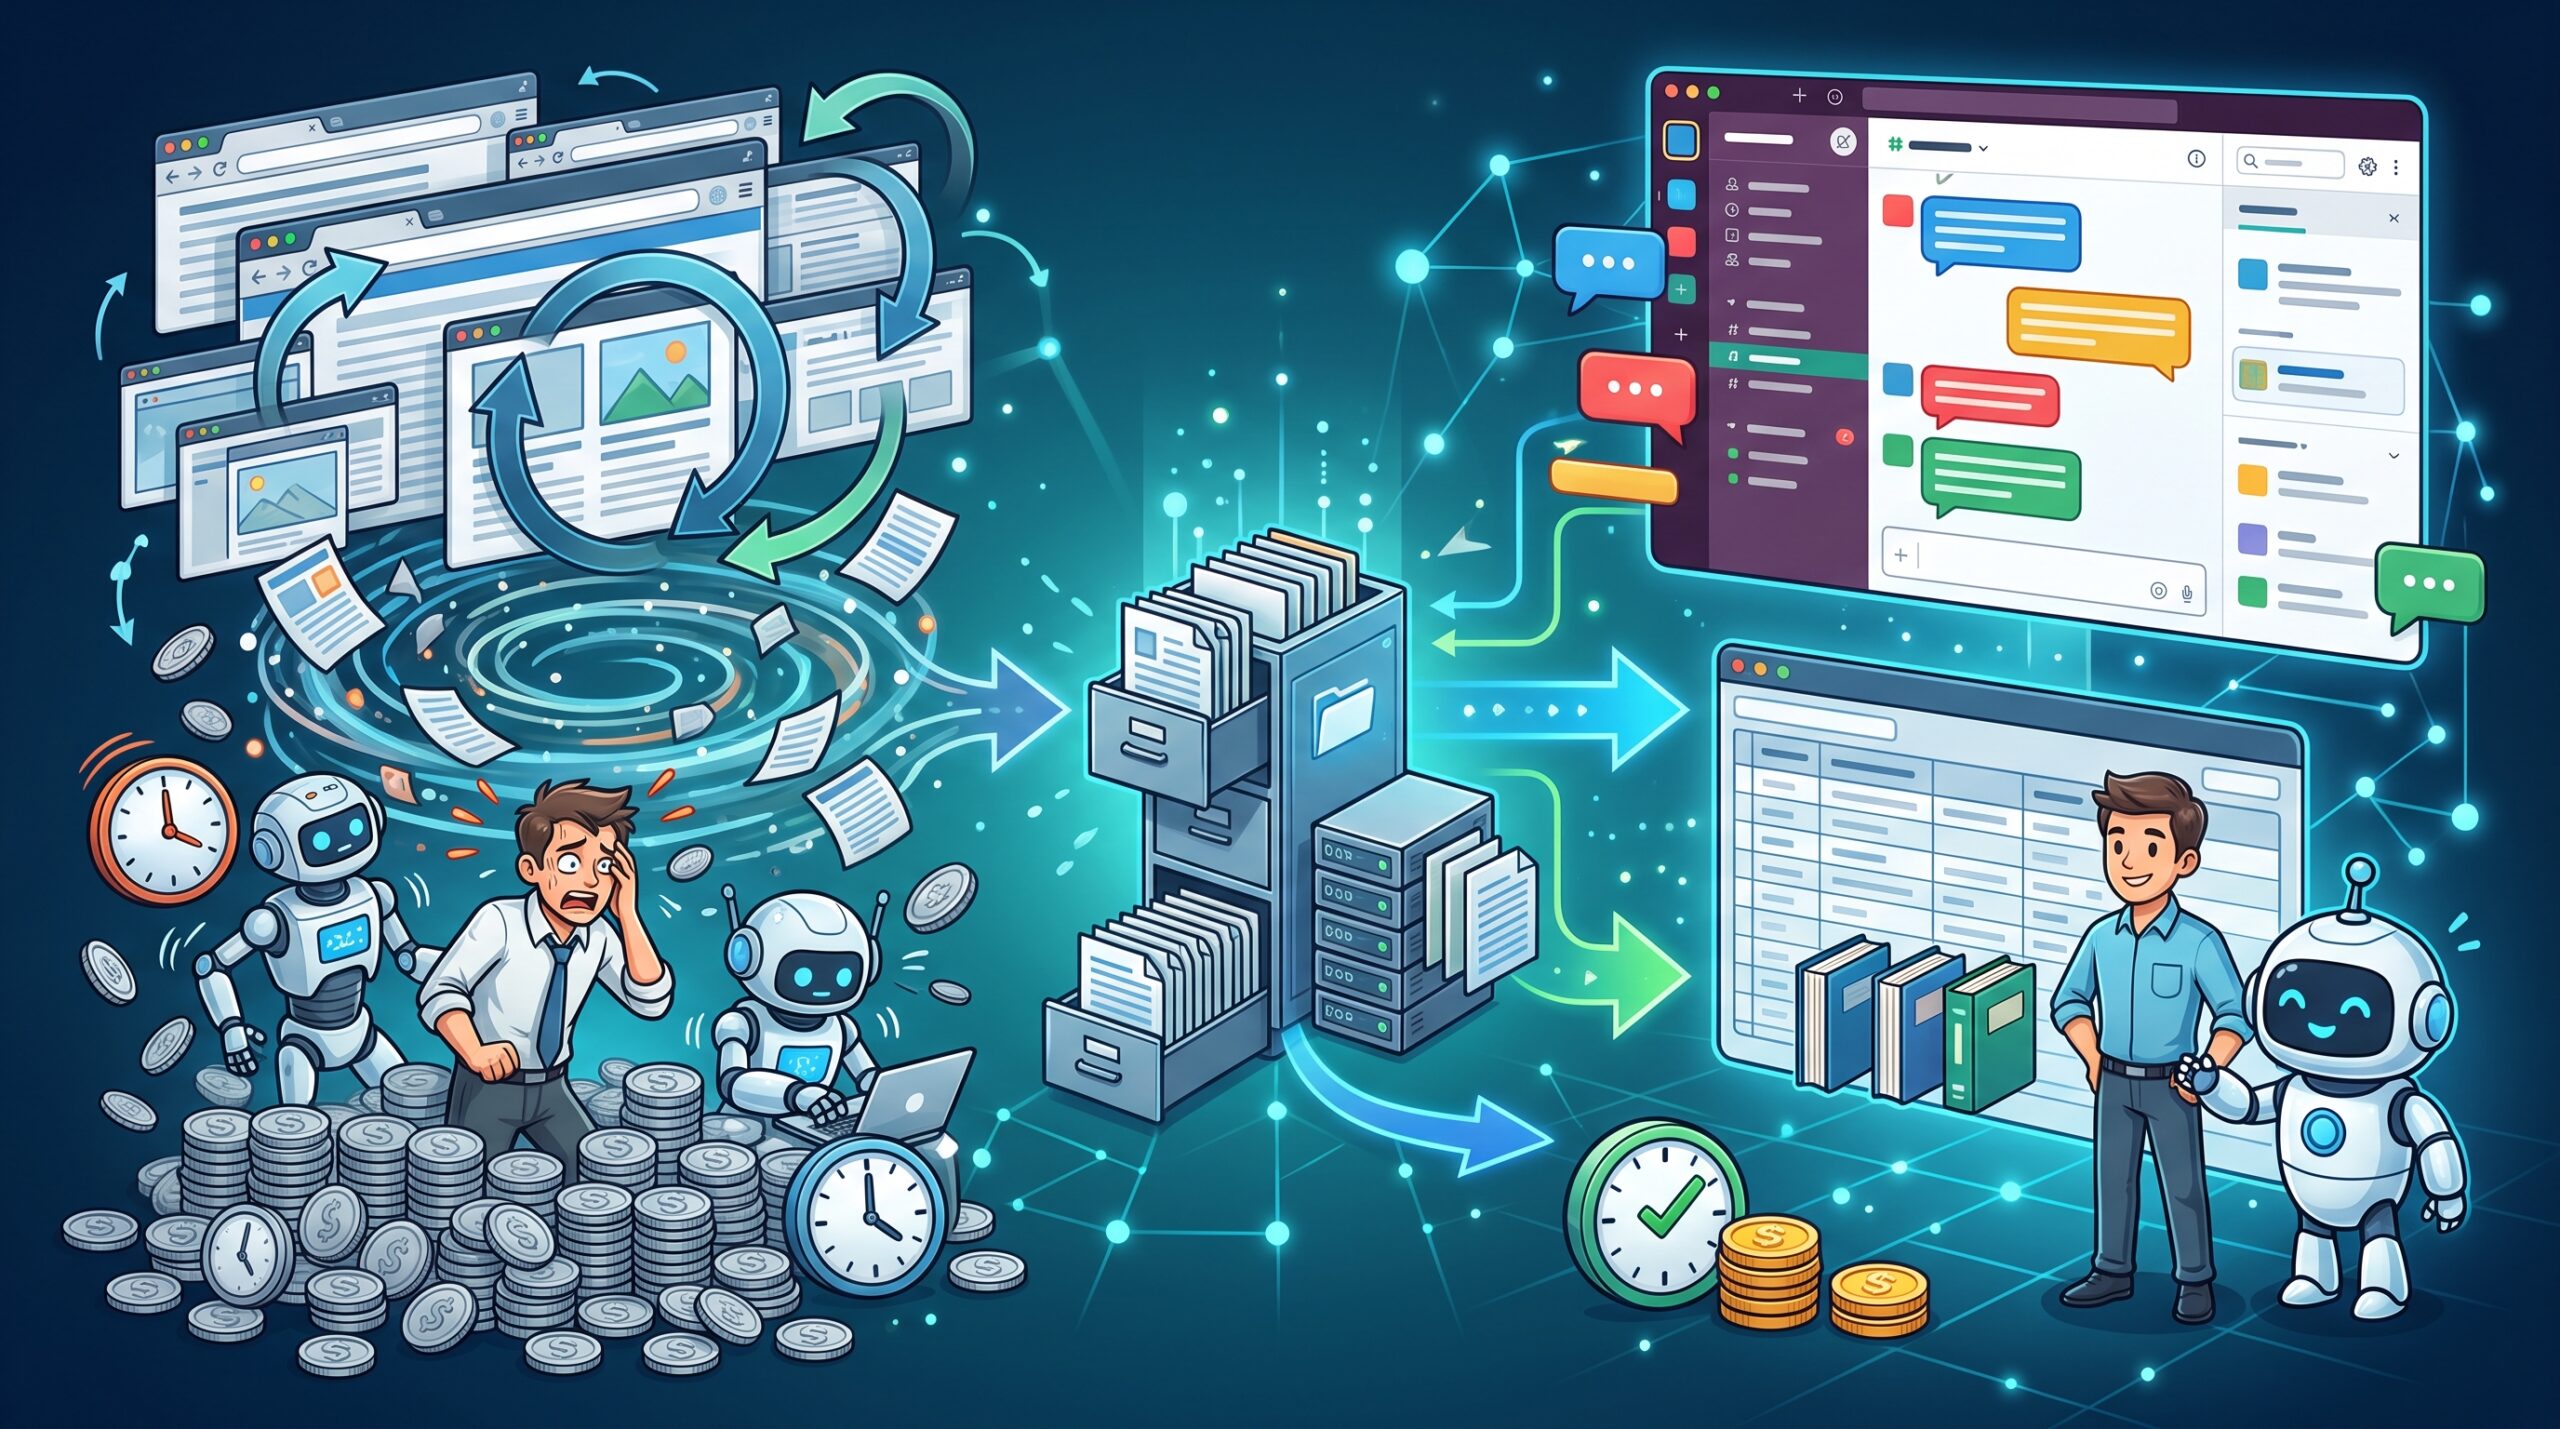
Asana said a validation effort to optimize StackAI’s browser-operating AI brought the estimated model cost of a setup using GPT‑6.1 Sol to an average of $0.47 per run, with execution time of about four minutes. Compared with the original production setup, costs fell to about one-76th and processing became roughly five times faster.
The 76-fold reduction wasn’t achieved by changing models alone
Opening web pages, finding needed information and filling out forms: browser agents that handle tasks like these call a model repeatedly as they work, unlike an AI that generates an answer just once. At StackAI, which Asana acquired, customers can build automation workflows spanning multiple business apps without writing code.
The key point in these figures is that the roughly 76-fold reduction includes both process improvements and a model change. Even with the original Model B, optimization brought the estimated model cost per run down from more than $36.21 to $1.24. Using GPT‑6.1 Sol then lowered it further, to $0.47. Much of the reduction was achieved before the model was changed.
The cost cited here is an estimate of model usage fees. It does not mean that total costs—including server expenses and development and operations labor—fell by the same proportion.
If too much history is discarded, AI rereads the same pages
Frank Hidalgo, StackAI’s CTO, who led the investigation, asked GPT‑6 Astra in Codex to analyze the code and test proposed improvements. One problem it found was that page text and screenshot history were being resent with every model request. Fixed instructions and similar content could be reused, but the same mechanism was not being applied to the growing browsing history.
In addition, old images were deleted and text was truncated at nearly every step. Frequently rewriting history makes it harder for the cache—which reuses previously processed inputs to reduce costs—to work effectively. If too much information is removed, the AI may revisit pages it has already read. The system was structured so that efforts to shorten inputs could end up creating more work.
Instead of deleting images each time, clean them up after 20 accumulate
The tests used history-retention limits of 120,000 and 480,000 characters, with different cache and image-management policies, and ran 144 trials across four models. Each trial used the same task: collect six pieces of information about each of 32 books from a public demo catalog.
The optimized GPT‑6.1 Sol setup allowed screenshots to accumulate to 20, then kept only the most recent one. By cleaning them up in batches rather than deleting them every time, the team extended the period in which history could be reused without modification.
Even when comparing GPT‑6.1 Sol alone, revising cache and image management with a higher history-retention limit lowered the estimated model cost from $1.97 to $0.47. After optimization, 89% of inputs went through the cache, and those inputs cost 5% of the regular input rate. The effective design was not simply to reduce information, but to make retained information easier to reuse.
Completion rates changed, not just costs
History management also affected whether tasks could be completed. With GPT‑6.1 Sol, an answer was generated in only 3 of 18 runs when the retention limit was low. With a higher limit, answers were generated in all 18 runs, and all were correct, according to the company.
However, the comparisons of roughly one-76th the cost and about five times the speed need some qualification. The original setup included runs that hit the step limit before completion, so the figures of more than $36.21 in cost and more than 22.5 minutes indicate lower bounds. The main comparison figures are also averages of three runs per setup and come from this particular information-gathering task. They do not establish that the same reductions would apply to other websites or business workflows.
Models also have different strengths. After optimization, Model C cost $0.66 and took 3.5 minutes. It was more expensive than GPT‑6.1 Sol, at $0.47 and about four minutes, but ran faster. When deploying a model, cost and speed need to be compared separately.
AI runs the experiments; people review the changes
GPT‑6 Astra not only proposed improvements but also made code changes to standardize test conditions and ran the validation. A separate model session reviewed the work, and requests and results were recorded in Asana’s development platform, Command. Hidalgo said an investigation he estimated would take one to two months by hand was completed in about a week. That difference in duration is his estimate, not the result of a human-run comparative experiment.
The case shows that when assessing AI operating costs, there may be as much room to investigate how models are called and how history is maintained as there is to examine model pricing. Asana has applied the changes to StackAI’s browser-operation feature. The company plans to incorporate tests into its evaluation feature so customers and internal teams can compare costs, execution time and answer quality across different configurations.






Comments